Hi, I am Vidushee. I am a Research Fellow at X-NLP Lab, INSAIT, advised by Yuxia Wang. My main interests are multimodal learning, representation learning, any-to-any models, and diffusion. I also work on reinforcement learning and multi-agent systems.
Previously, I was a Research Intern at Halmstad University, working on any-to-any multimodal generation and alignment, advised by Shengzhi Li and Dr. Prayag Tiwari. I worked as a Research Engineer at Lexsi Labs and an AI Engineer at TUM & SAP. I was also a Computer Vision Research Affiliate at Georgia Institute of Technology, advised by Prof. Vijay Madisetti, where I worked on visual grounding in vision-language models. I graduated with a B.Tech in Computer Science (AI) from Bennett University.
X-NLP Lab, INSAIT
Research Fellow
Feb 2026 - Present
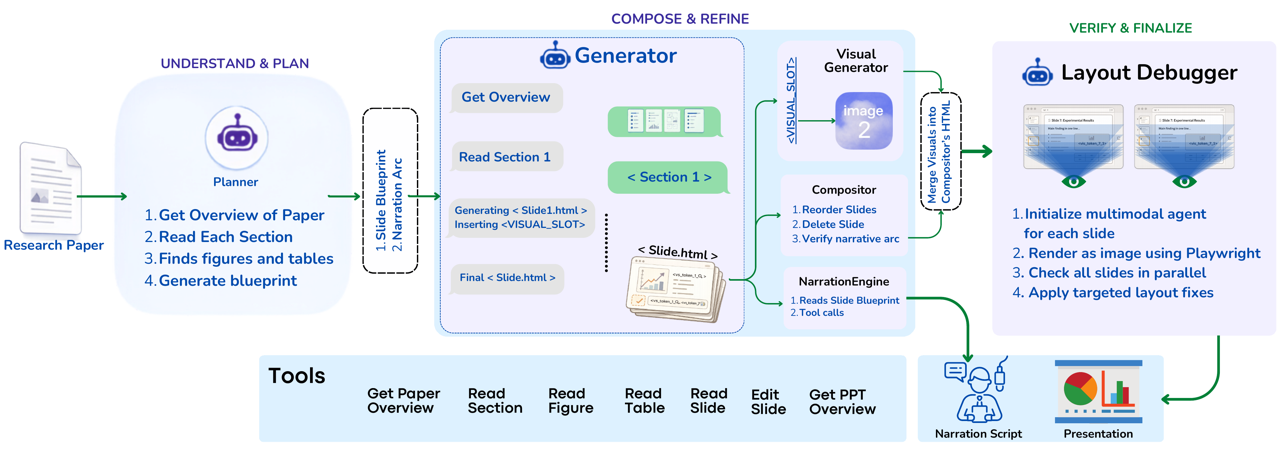
Working with Yuxia Wang on continual learning for personalized models that update after each user interaction. Built a multimodal system for personalized slide generation, with about 10% higher F1 than Claude Code and generation twice as fast and cheaper than Manus, Skywork, and Kimi.
Lexsi Labs
Research Engineer
Jun 2026 - Aug 2026
Built an agentic training framework for autonomous retraining of LLMs and VLMs. Led a three-stage move to an isolated execution environment to scale production agents.
Halmstad University
Research Intern
From Sep 2024
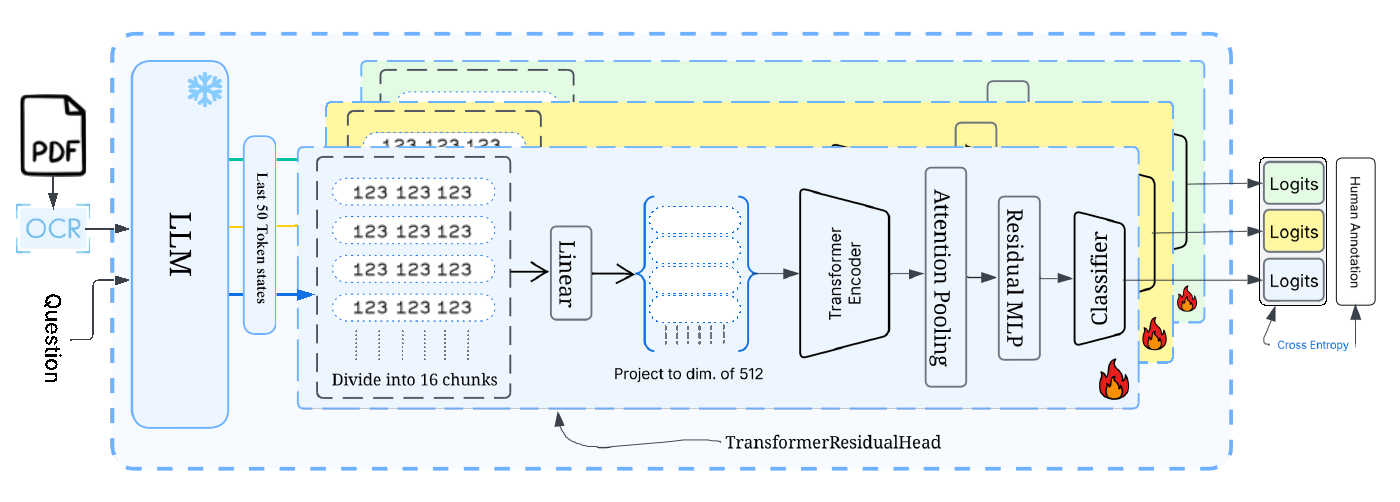
Advised by Shengzhi Li and Dr. Prayag Tiwari. Trained Qwen3.5-27B with SkyRL and Claude Code in a Harbor environment for autonomous scientific research. Built an asynchronous off-policy RL sampler for the Tinker API, cutting training cost from $1M to $300K. Worked on reward modeling for scientific question generation (Findings of ACL 2026), reduced visual information loss in any-to-any models, and replaced the NExT-GPT image decoder with FLUX.
Technical University of Munich & SAP
AI Engineer
Mar 2025 - May 2025
Built AI agents for SAP UI navigation and testing. Converted traditional test scripts to VLM-based navigation with 100% test coverage. Built a pipeline to fix failed scripts, reducing maintenance from weeks to hours.
Georgia Institute of Technology
Computer Vision Research Affiliate
Aug 2024 - Dec 2024
Designed a plug-and-play Visual Grounding framework. Outperformed SOTA models and GPT-4V by mIoU of 0.11 & 0.48 on RefCOCOg. Extended the grounding framework to accept multiple modalities (image, video).
Zocket AI
Computer Vision Intern
Apr 2024 - Aug 2024
Built a pipeline to fetch visually semantic videos from 100K+ videos with sub-0.5s latency. Designed an AI module for cross-platform ad resizing. Fine-tuned inpainting models for text-based background generation.
@inproceedings{sharma-etal-2026-preference,
  title={Preference Optimization for Review Question Generation Improves Writing Quality},
  author={Sharma, Karun and Vats, Vidushee and Li, Shengzhi and Wang, Yuxiang and Sun, Zhongtian and Tiwari, Prayag},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2026},
  year={2026},
  pages={25081--25104},
  doi={10.18653/v1/2026.findings-acl.1256},
  url={https://aclanthology.org/2026.findings-acl.1256/}
}
@inproceedings{sharma2025think,
  title={Think to Ground: Improving Spatial Reasoning in LLMs for better Visual Grounding},
  author={Sharma, Karun and Vats, Vidushee},
  booktitle={ICLR 2025 Workshop on Reasoning and Planning for Large Language Models},
  year={2025}
}

@INPROCEEDINGS{10651096,
  author={Sharma, Karun and Vats, Vidushee and Singh, Abhinendra and Sahani, Rahul and Rai, Deepak and Sharma, Ashok},
  booktitle={2024 International Joint Conference on Neural Networks (IJCNN)},
  title={LLaVA-PlantDiag: Integrating Large-scale Vision-Language Abilities for Conversational Plant Pathology Diagnosis},
  year={2024},
  pages={1-7},
  doi={10.1109/IJCNN60899.2024.10651096}
}

@INPROCEEDINGS{10330945,
  author={Gupta, Ujjwal and Golash, Roshan and Vats, Vidushee and Sharma, Karun},
  booktitle={2023 International Conference on Emerging Techniques in Computational Intelligence (ICETCI)},
  title={An Improved Hybrid Model for Target Detection},
  year={2023},
  pages={265-270},
  doi={10.1109/ICETCI58599.2023.10330945}
}